Config over code
One YAML block per table: source or logic, key, merge strategy.
Config over code
One YAML block per table: source or logic, key, merge strategy.
Dependency tree
Parents are read from your SQL and PySpark files. A table starts when its parents have succeeded.
Merge strategies
scd1, scd2, replace and append, with sequence ordering, soft or hard deletes and snapshot merges for full extracts.
Databricks and Fabric
The same config runs on local Spark, Databricks and Fabric.
systems: crm: type: csv path: data/customer.csvbronze: tables: customer: source: { system: crm, object: account } business_key: [accountid] strategy: scd1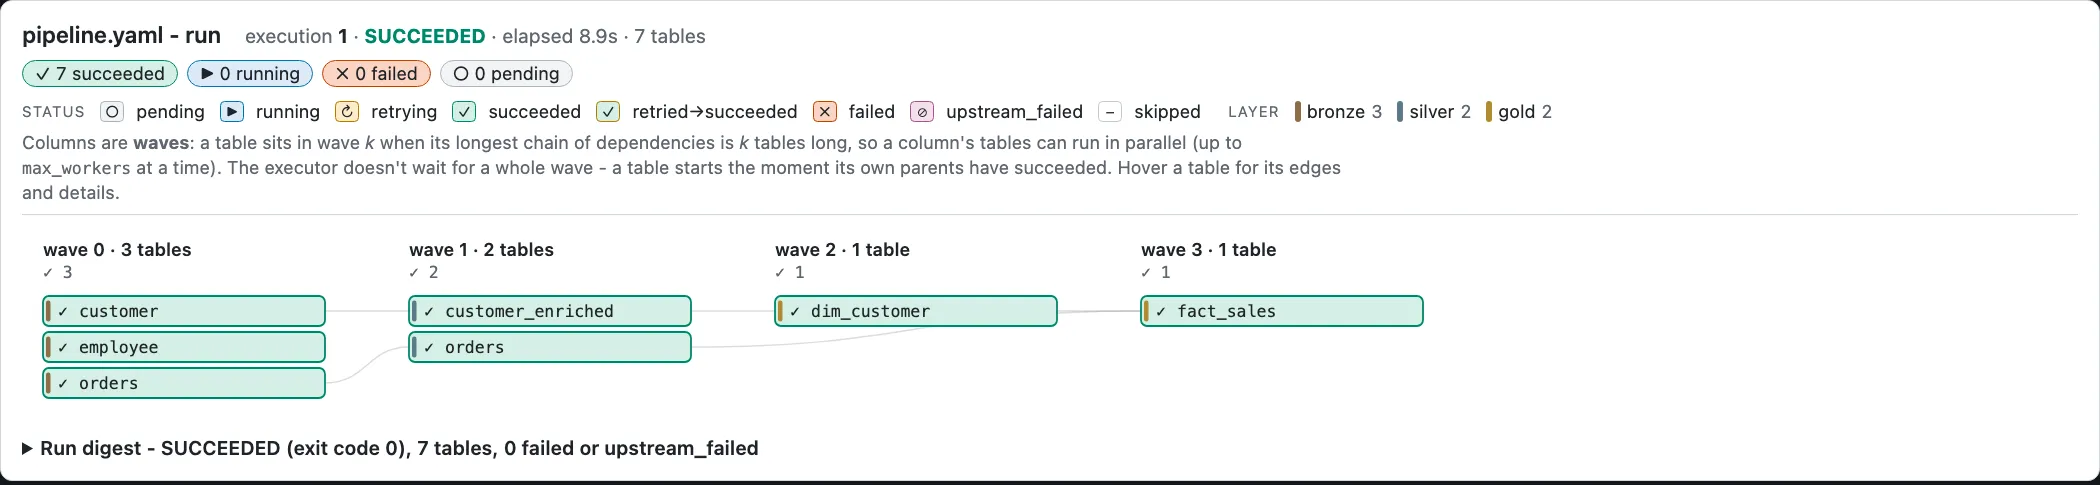
pip install pipetree-metaAdd [spark] to run on a laptop. Databricks and Fabric bring their own Spark: install without it. See Install.